Every answer carries its source document and the SQL that ran.
Documents and structured data
in a single question.
Documents and several structured data sources in a single question, with big-data ETL running under the same permissions and policy. Whatever must be masked stays masked wherever the query runs.
A question that used to cross three systems ends in one.
Document repository, data catalog and de-identification policy live in one environment. The person asking does not need to know which system holds the answer.
Documents and the database answer together
Documents, unstructured and structured data live in one repository, one catalog, one question box. Structured sources connect over PostgreSQL, MySQL, StarRocks and Iceberg. One question gets an answer from documents and the database together, with the source file name, page and the SQL that ran.
Whatever must be masked stays masked wherever the query runs
Personal data is masked at read time by a policy set once. Document queries and SQL results fall under the same policy. The original is never touched.
People and AI agents see only what they are allowed to
Viewing, search, SQL and ETL all pass through the same permission gate. Run the same query as two users with different permissions and different values get masked.
Shown on real screens.
These slots will hold real screens captured on a demo tenant. All personal data is fictitious.
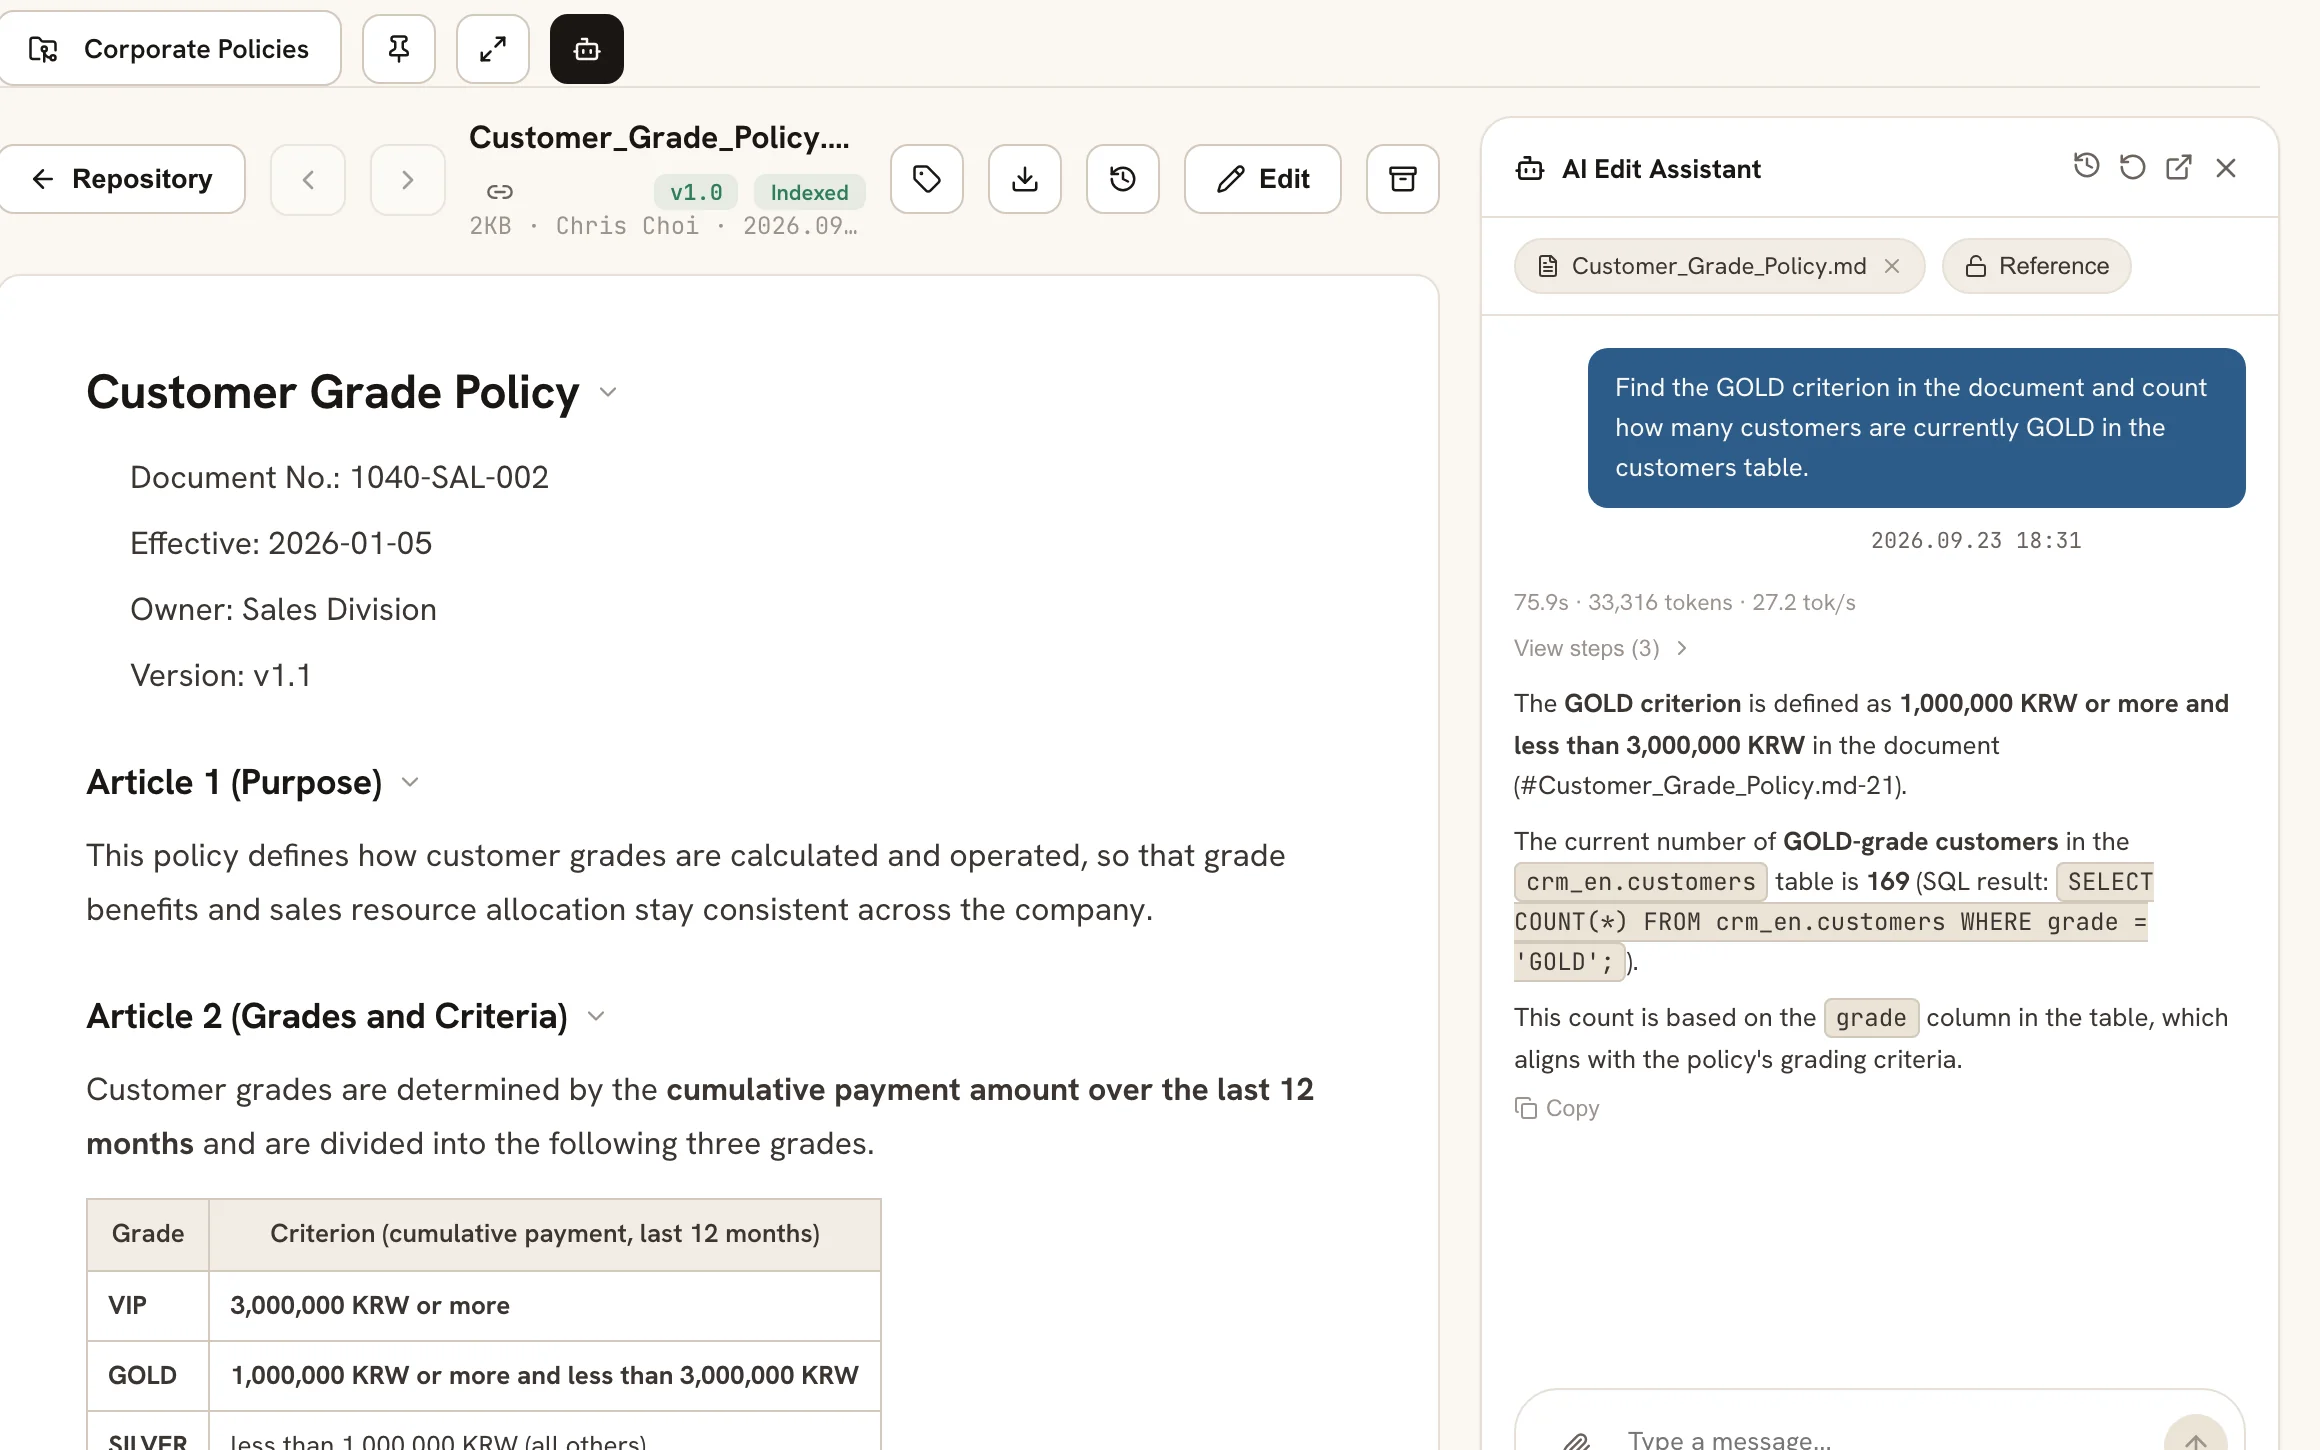
Documents + data in one conversation
Headcount policy from the document, current headcount from the hr table. One answer carries the source file name, page and the SQL that ran.
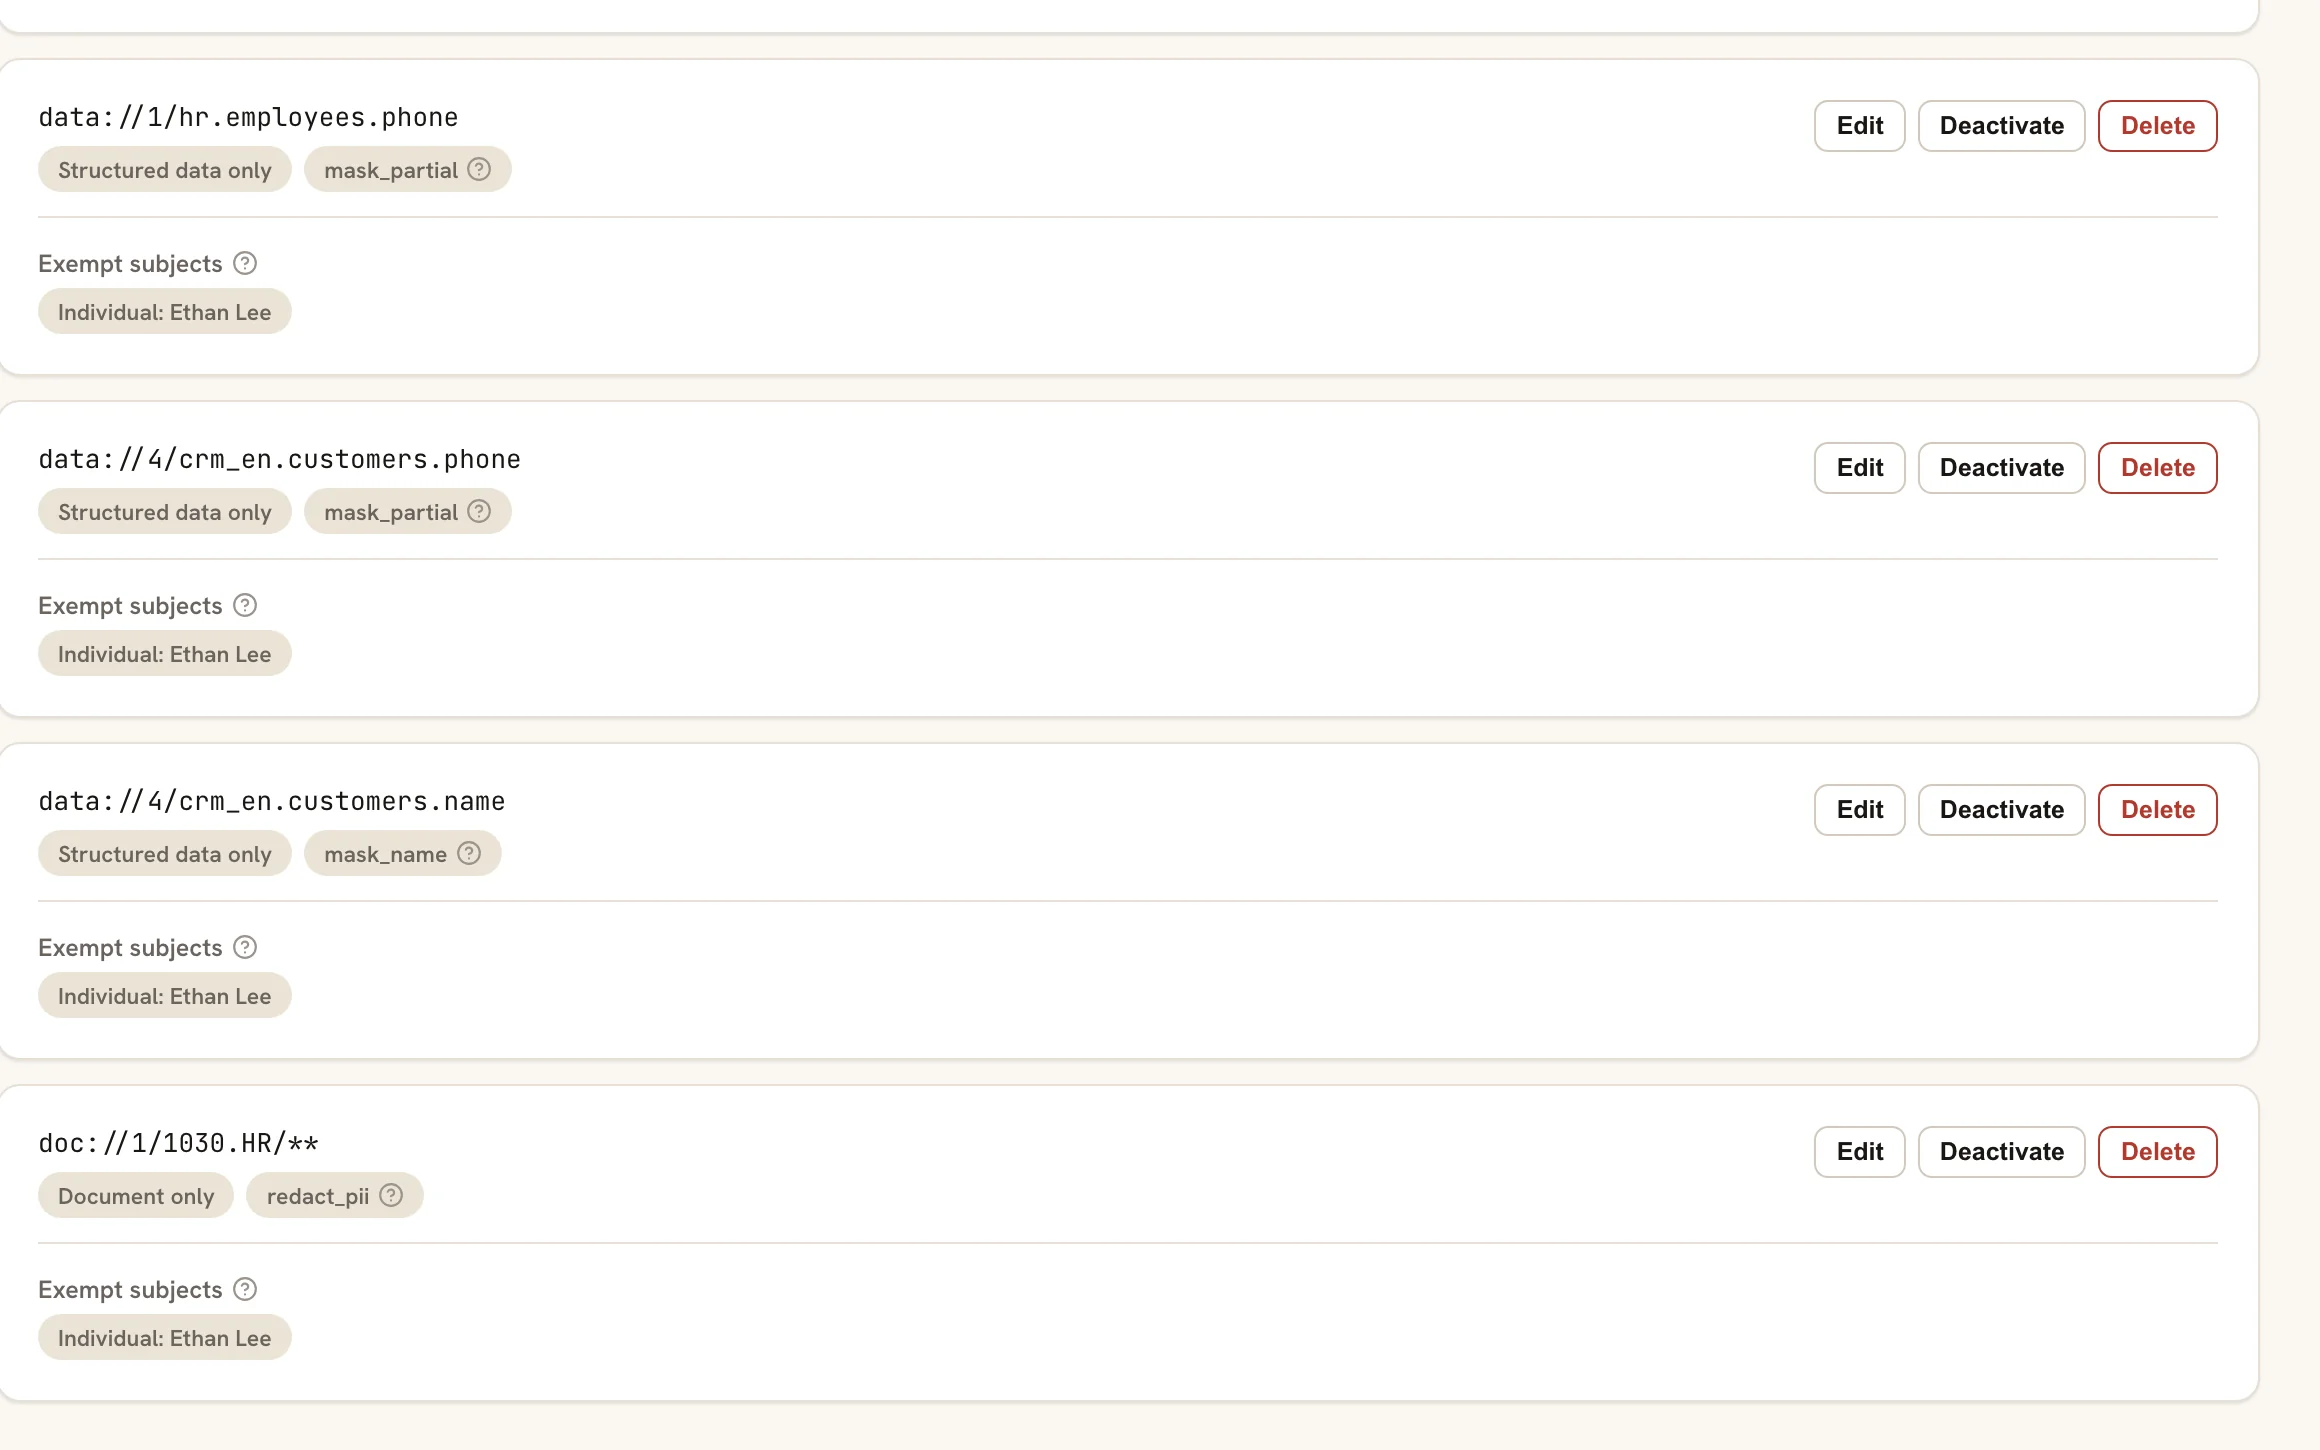
Content filter bindings
doc:// document paths and data:// table columns share one de-identification policy. Exceptions only for named subjects. Anyone who is not an exempt subject sees masked values only.
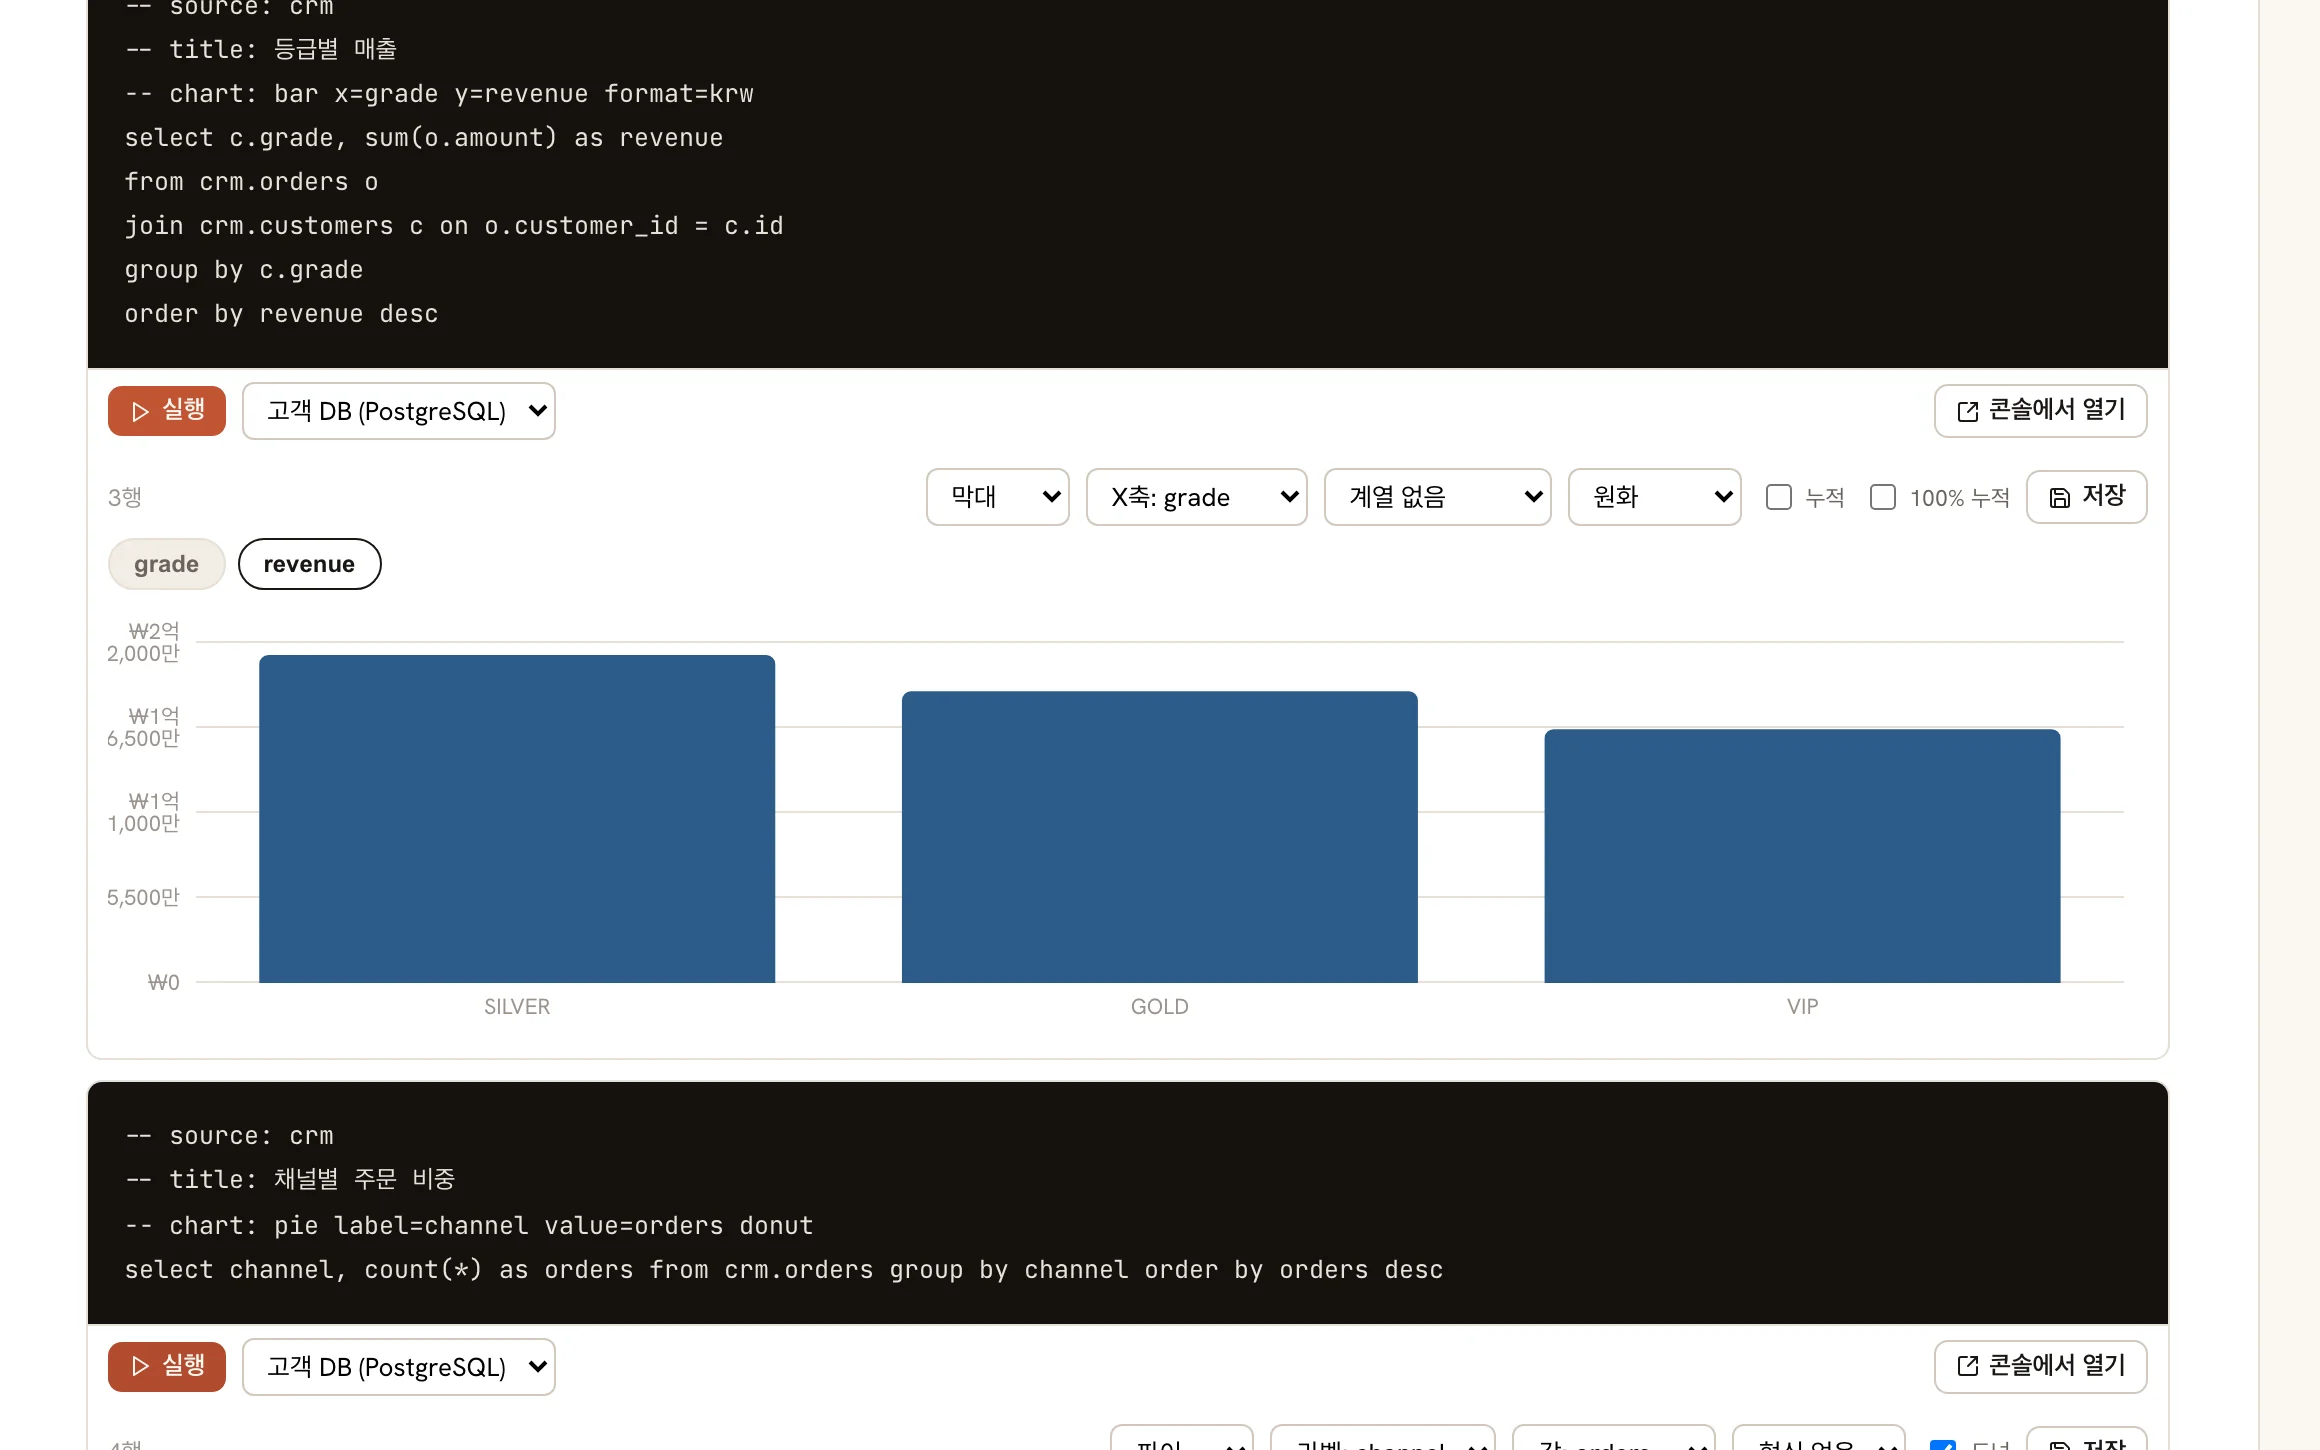
Structured-analysis notebook (Korean UI)
Several SQL cells in one document, each rendered as a different chart (line, bar, pie). Switch chart types per cell and try them out. EN capture not yet available.
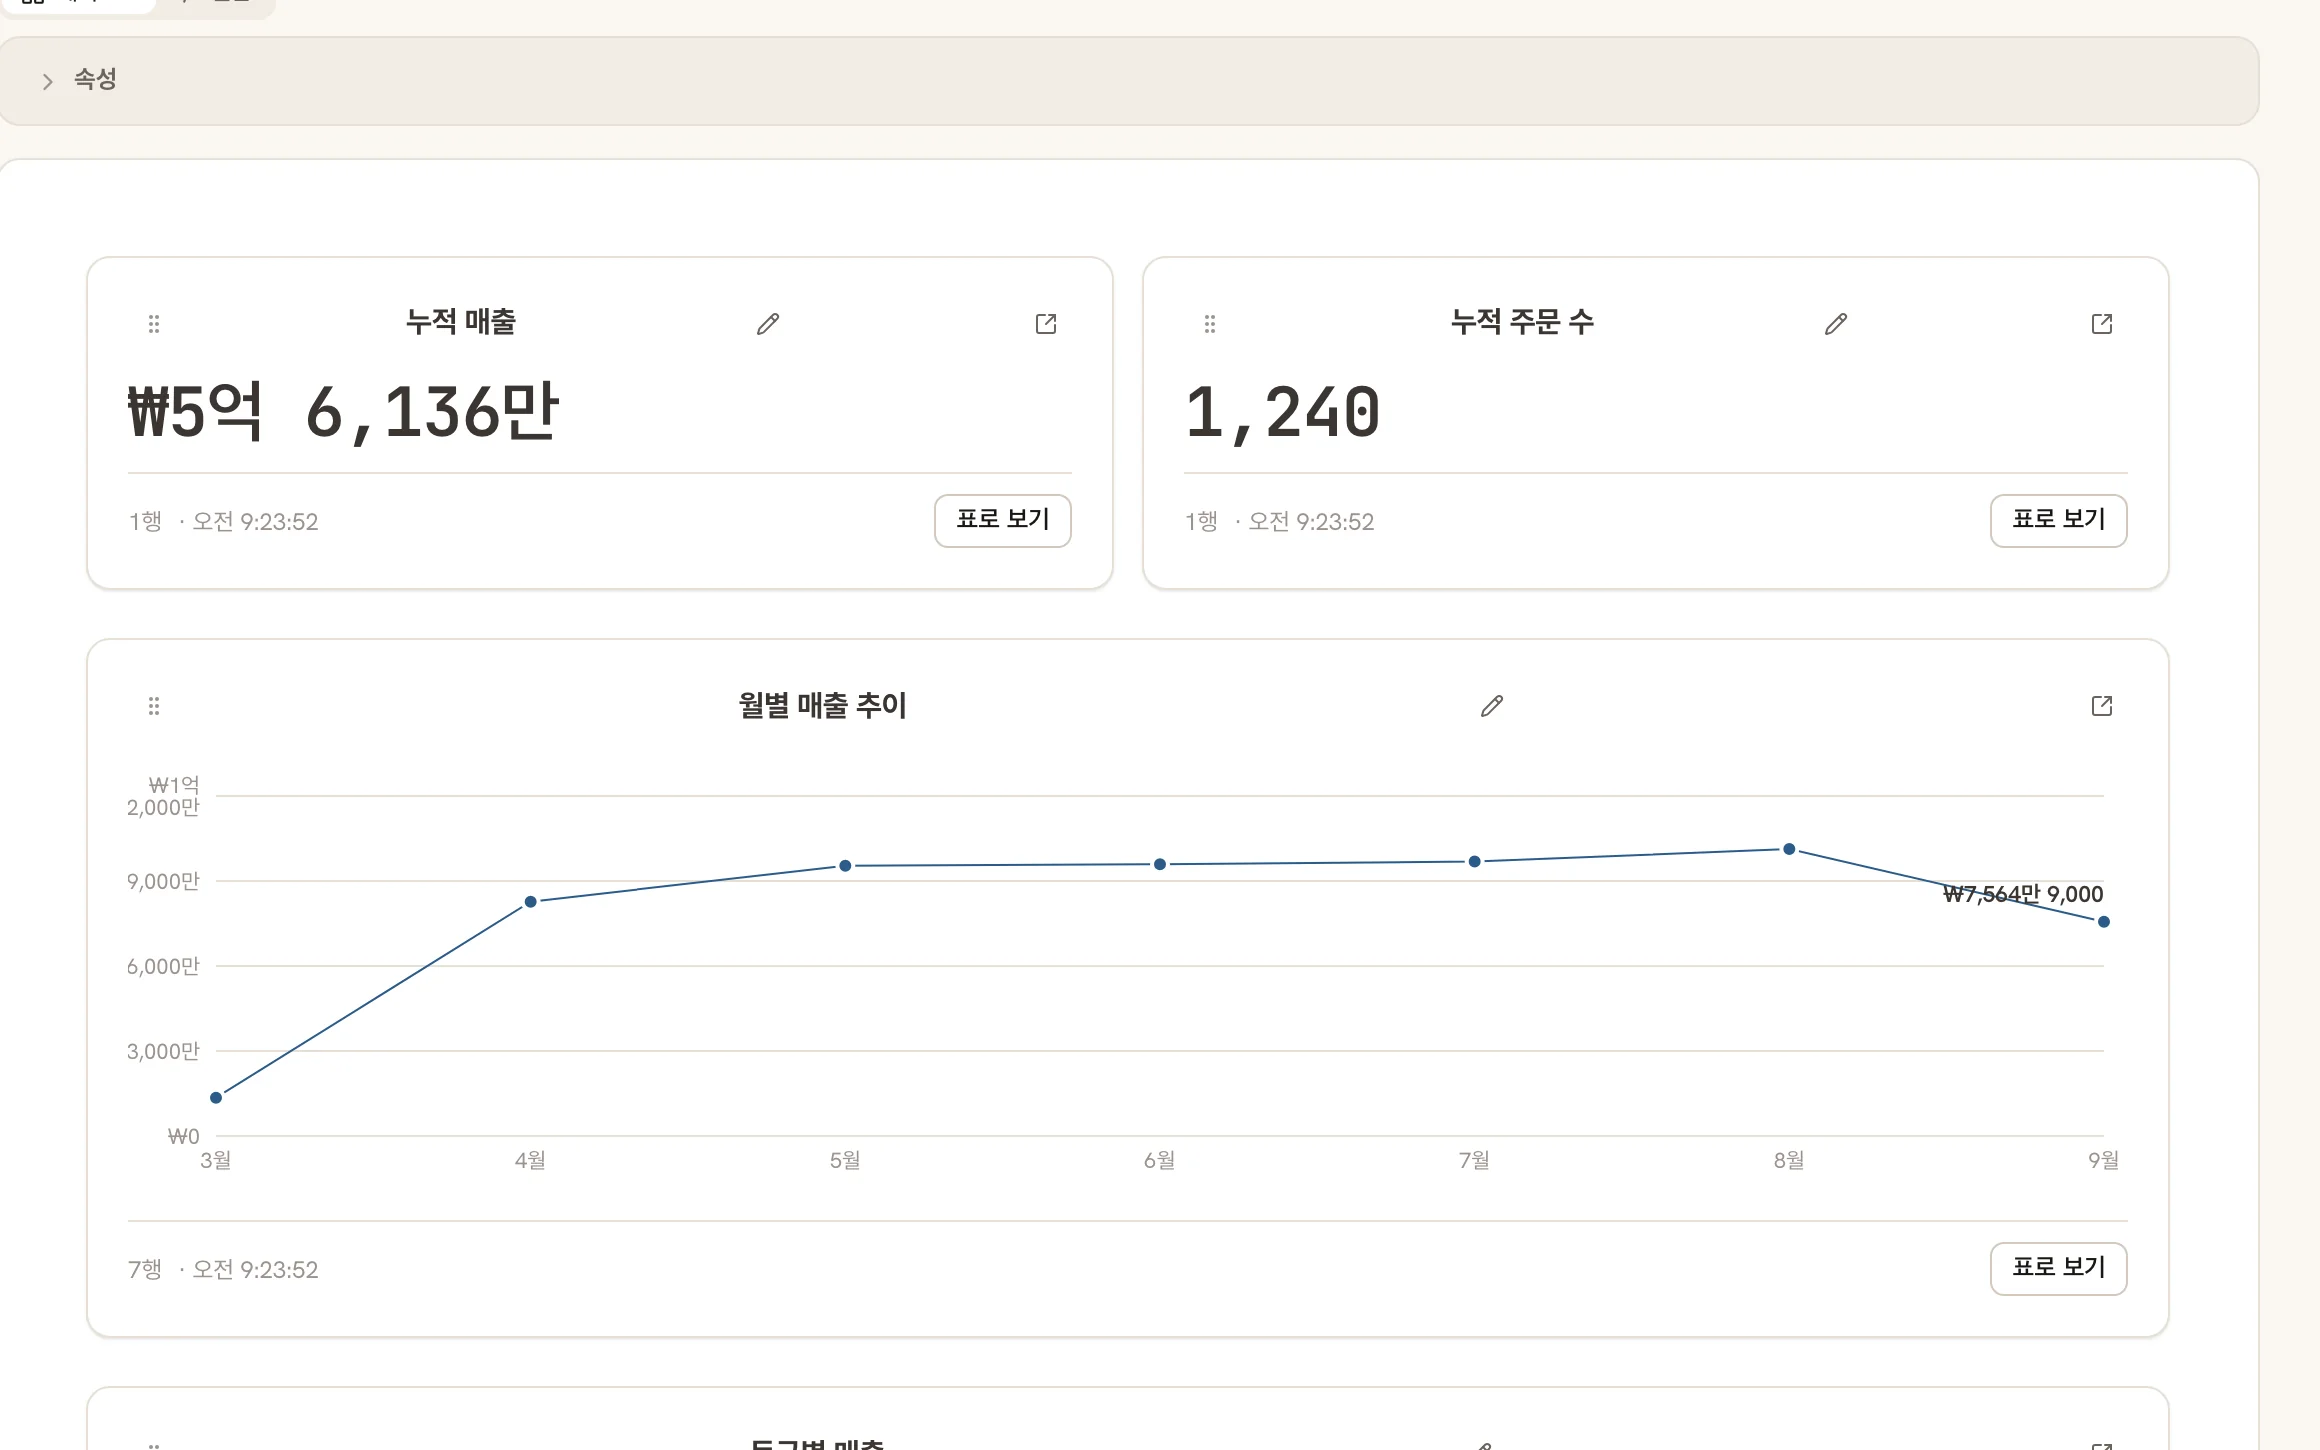
MD dashboard (Korean UI)
The same data laid out as KPI, trend, comparison and share cards in one dashboard document — the document itself is the dashboard. EN capture not yet available.
As it matures
Authoring, gating, approval and monitoring of ETL manifests happen in PAASUP DNA; large-scale execution is taken by PAASUP DIP, the platform underneath. Once you need to run policies and keep their execution as evidence, the next step is PAASUP ACE. Either way, permissions and policy carry down as is.
See PAASUP ACE →FAQ
PAASUP DNA is an agentic analysis service that asks documents and structured data in one question. Whatever must be masked stays masked wherever the query runs.
01How is PAASUP DNA different from a BI tool?
It is not a charting tool. It reads documents and data together. One question returns the evidence from documents and the SQL result side by side, with sources attached.
02Can I query data that contains personal information?
Yes. Personal data is masked at read time by a content filter policy set once. The same policy applies to documents, search and SQL, and the original never changes.
03Which data sources can I connect?
Structured sources such as PostgreSQL, MySQL, StarRocks and Iceberg. Permissions are managed in the same catalog as document repositories.
04What happens when the data gets large?
Large-scale distributed processing is handed to PAASUP DIP, the platform underneath. Where the processing runs changes; who can see what does not.
05How do I start?
Request a consultation through the contact form and we start a PoC on one data source.
One source is enough to see it.
In the consultation we pick one data source and one document repository. Run the same question as two people with different permissions within that scope and you are done. Connecting the rest comes after.